TL;DR. Brain-DiT learns multi-state fMRI representations through metadata-conditioned diffusion. Across seven downstream tasks, the study finds advantages over the compared reconstruction and alignment objectives, while showing that different prediction tasks prefer different feature scales.
Can one representation work across rest, tasks and sleep?
A resting scan, a task experiment and a sleep recording capture different aspects of brain activity. Training on a narrow range of states can limit what a foundation model transfers to new settings.
Brain-DiT studies two connected choices: what objective should pretraining optimize, and how should a model account for differences between populations and recording contexts? It uses generative denoising as the learning task and metadata as conditioning information.
Turn denoising into a representation-learning task
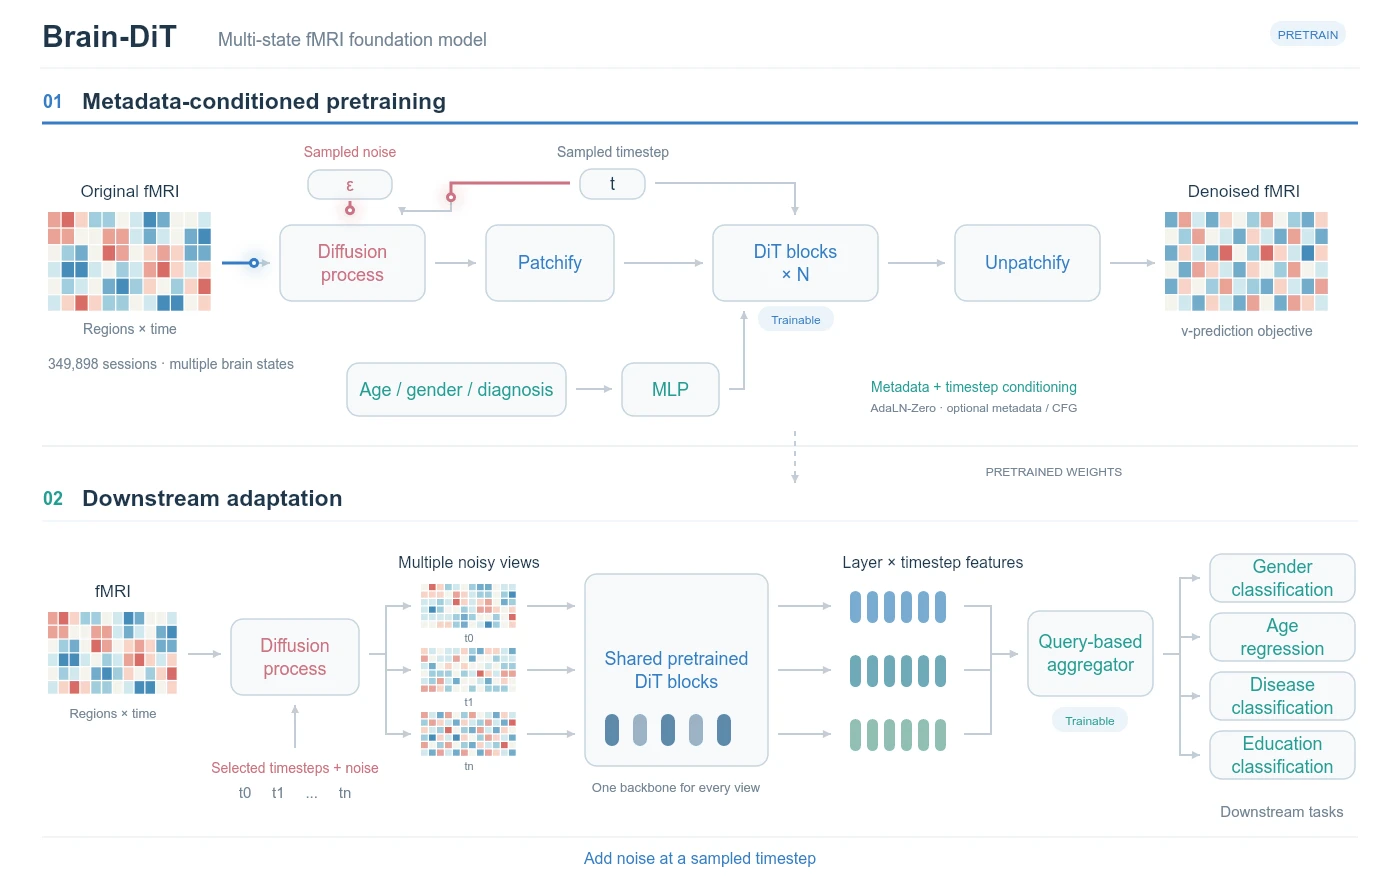
Diffusion training progressively corrupts a signal with noise and teaches a model to recover its structure. Brain-DiT uses this process on regional fMRI time series, with metadata to describe the recording context. The pretrained model then becomes a source of features for downstream prediction.
Animation from the author’s GitHub ↗
Method overview. The top pathway is metadata-conditioned diffusion pretraining. The lower pathway extracts features at multiple layers and noise timesteps and combines them with a query-based aggregator for classification or regression. Source paper ↗
Bring different brain states into training
Regional time series cover resting, task, naturalistic, disease and sleep states. The author repository distinguishes the full curated collection from the pretraining split and holds out three datasets for external evaluation.
Learn through conditioned diffusion
A Diffusion Transformer learns to denoise signals across noise levels while incorporating metadata. This exposes the model to both detailed signal structure and broader patterns.
Combine features for a specific task
Downstream adaptation extracts features at several diffusion timesteps and network layers. A query-based aggregator combines them for classification or regression, allowing the task to select useful representational scales.
| Collection | Datasets | Samples |
|---|---|---|
| Full curated collection | 24 | 349,898 |
| Pretraining | 21 | 317,864 |
| Out-of-distribution evaluation | 3 | Held out of pretraining |
Samples are training/evaluation units, not unique participant counts.
The useful representation depends on the question
The evaluation asks both whether diffusion is a useful pretraining objective and which of its representations a downstream task should use.
Diffusion and metadata both contribute
Across seven tasks, diffusion pretraining performs better than the compared reconstruction and alignment objectives. Adding metadata conditioning yields further improvements in the study’s ablations.
ADNI and age prediction favor different scales
ADNI classification benefits more from global semantic representations. Age and sex prediction rely comparatively more on fine-grained structure. Features from different timesteps and layers are therefore complementary, which motivates the task-specific aggregator.
Feature extraction is part of the model
Brain-DiT makes the choice of representation explicit: a pretrained backbone can provide multiple views of the same signal, and the downstream task can learn which views to combine. This is particularly useful when the target task differs from the states and populations that dominate pretraining.
Explore the project
Use the repository and linked checkpoint to study multi-state ROI representations or task-specific feature aggregation. Match the input atlas, preprocessing and conditioning fields to the released pipeline.
A Universal Multi-state fMRI Foundation Model with Metadata-Conditioned Pretraining
Research post by fMRI Atlas, based on the original study linked above.
Read the paper’s abstract
Current fMRI foundation models primarily rely on a limited range of brain states and mismatched pretraining tasks, restricting their ability to learn generalized representations across diverse brain states. We present Brain-DiT, a universal multi-state fMRI foundation model pretrained on 349,898 sessions from 24 datasets spanning resting, task, naturalistic, disease, and sleep states. Unlike prior fMRI foundation models that rely on masked reconstruction in the raw-signal space or a latent space, Brain-DiT adopts metadata-conditioned diffusion pretraining with a Diffusion Transformer (DiT), enabling the model to learn multi-scale representations that capture both fine-grained functional structure and global semantics. Across extensive evaluations and ablations on 7 downstream tasks, we find consistent evidence that diffusion-based generative pretraining is a stronger proxy than reconstruction or alignment, with metadata-conditioned pretraining further improving downstream performance by disentangling intrinsic neural dynamics from population-level variability. We also observe that downstream tasks exhibit distinct preferences for representational scale: ADNI classification benefits more from global semantic representations, whereas age/sex prediction comparatively relies more on fine-grained local structure. Code and parameters of Brain-DiT are available at the code repository.
Dataset accounting note: The supplied abstract describes 349,898 sessions. The current author repository distinguishes 349,898 curated samples across 24 datasets from 317,864 pretraining samples across 21 in-distribution datasets; three out-of-distribution datasets are held out. These are not participant counts. The comparison above follows the repository’s explicit split.
BibTeX
@inproceedings{xia2026braindit,
  title={Brain-DiT: A Universal Multi-state fMRI Foundation Model with Metadata-Conditioned Pretraining},
  author={Xia, Junfeng and Ye, Wenhao and Pan, Xuanye and Shen, Xinke and Wang, Mo and Liu, Quanying},
  year={2026},
  booktitle={Medical Image Computing and Computer Assisted Intervention -- MICCAI 2026},
  publisher={Springer Nature Switzerland},
  volume={16894},
  url={https://papers.miccai.org/miccai-2026/0120-Paper1362.html}
}